
NAZARE
Manufacturing data infrastructure on three servers
Operate connections, ingestion, storage and queries together in an on-site cluster.
Explore the product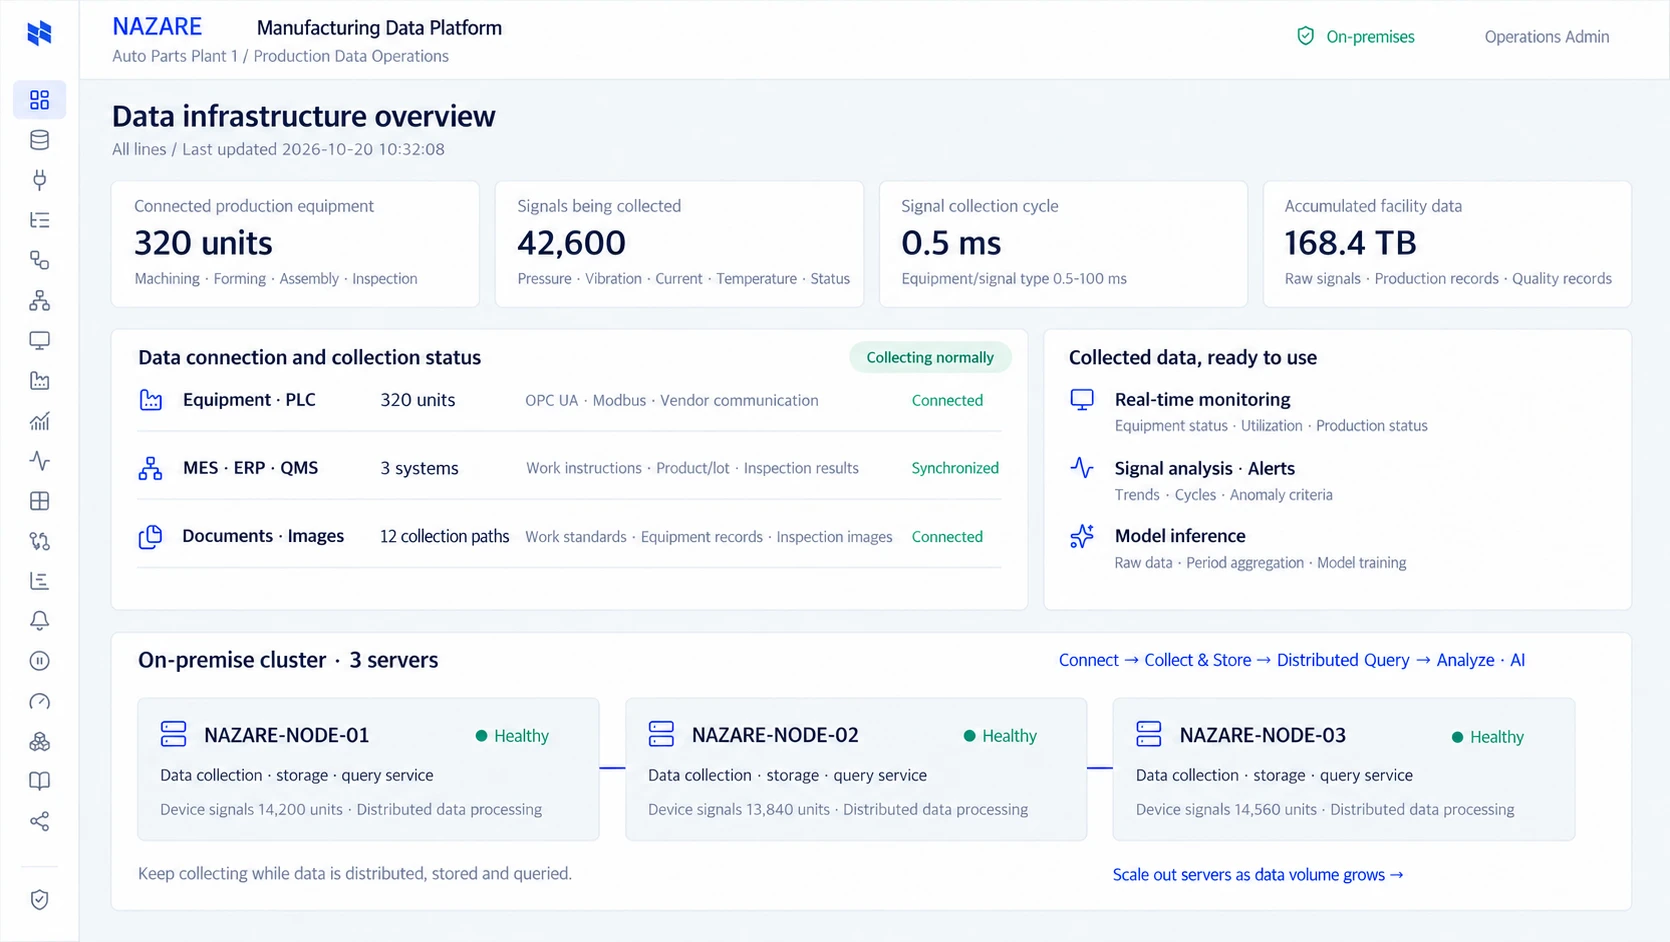
Resources
Design data flows and ownership around sampling, retention, queries and AI workloads.
The approach
Fit sites with restrictions on data leaving
Use data within the scope of each task
Start new uses within company policy
Plan beyond the initial deployment
NAZARE
Operate connections, ingestion, storage and queries together in an on-site cluster.
Explore the productDetails
Map generation, ingestion, preparation, storage, queries, model inputs and retirement. Assign latency, recovery and ownership at each step. Raw retention and change history support reproducible analysis beyond the dashboard.
Live alarms need fresh signals; historical queries select relevant files and columns. Estimate volume, retention and concurrency per path. Include sampling, value size, replication, backup and aggregation, not tag count alone.
Agree identities, types, time zones, units, cadence and errors between equipment, MES, quality and the platform. Apply the same discipline to partner-facing queries.
Separate read and action privileges, documenting tool inputs, outputs, failures and approval scope for NAVIS.
Observe infrastructure, quality, pipelines, queries and serving. Validate restoration as well as backup creation. Include tenant isolation, access, version changes and support ownership in the deployment scope.
Start together
Tell us about your equipment, data and priorities to review a path from connection to operations.